Beating RL With Reflection: GEPA and Optimize Anything —…
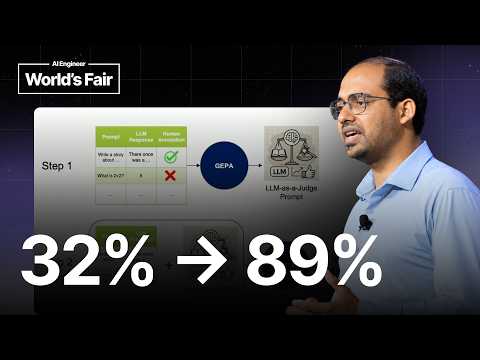
Talk by Lakshya A. Agrawal (UC Berkeley Sky Computing Lab, creator of GEPA) on reflective prompt optimization versus reinforcement learning. GEPA has a model read full execution traces—chains of thought, tool calls, error messages—and write improved prompts, with a Pareto pool of candidates to avoid local optima; the creator states it matched GRPO's gains after one reflection round on three examples versus 25,000 rollouts. The talk also covers Optimize Anything, which applies the same text-and-score optimization beyond prompts, including benchmark results such as lifting Gemini Flash on ARC-AGI from 32.5% to 89.5%, tuning an AMD NPU coding agent from 4% to 30%, improving a GPT-5 mini coding agent on Go issues from 24% to 93%, production use at Databricks, learning evals from production traces, and co-optimizing prompts and weights. Timestamps cover the sample-efficiency bottleneck, how GEPA works, its API, optimization modes, and adoption.
# Channel Presentation Observations — "Beating RL With Reflection: GEPA and Optimize Anything"
## Source Evidence Scope
- **Supplied:** title and full conference-style talk transcript.
- **Not supplied:** curated channel metadata (about page, playlists, etc.).
- **Format observed:** a single research/technical presentation delivered by a named speaker on behalf of a team ("my name is Lakshia Agraal and today I'll be presenting on behalf of a very large effort").
## Intended Audience
The talk addresses a **technical AI practitioner audience**, not a general one. Evidence:
- **ML research literacy assumed without explanation:** terms like *gradient descent*, *GRPO*, *SFT*, *Pareto-based candidate selection*, *rollouts*, and *LLM-as-a-judge* are used directly. Only brief, illustrative analogies are provided (e.g., the one-word prompt change "generate a oneline summary" → "generate a 10-line summary").
- **Engineering decision-makers:** the talk repeatedly emphasizes practical deployment concerns — "human engineering teams... spend weeks of their time manually tweaking," cost/latency figures ("90x cheaper," "cutting down the execution time... by almost 50%"), and adoption by companies ("people at Snorkel had already improved some of their internal benchmarks with it").
- **Hands-on users:** calls to action are tool-oriented — "You can go to this QR code and you can run this example right now," "You can find it in the JPA repository and it's fully open source," "It can plug into any framework, any model and it has absolutely zero hard dependencies."
## Claimed Scope
The speaker makes broad, explicit scope claims on behalf of the work (creator claims, not independently verified):
- **Beyond prompts:** "if you can write it as text and score it, JPA can optimize it" — covering CUDA kernels, agent harnesses, cloud scheduling policies, and agent skills.
- **Sample-efficiency positioning:** positioned as a solution where RL is infeasible — "Japa in just one round of reflection using just three data points is already able to get twice the performance gains that gpo got after 25,000 rollouts."
- **Industry adoption claims:** named organizations are cited — AMD, Snorkel, Databricks, Dropbox, Shopify, OpenAI ("OpenAI also wrote a blog post about how you can build self-improving AI systems with Japa").
- **Counter-positioning claim:** "as models get better they will get better at instruction following... the better the instruction was claopus actually jumped much higher" — directly rebutting the expectation that prompt optimization declines in relevance.
## Self-Description Evidence
- **Research-group presentation style:** framed as a team effort with associated papers ("we recently had this paper called learning fast and slow").
- **Open-source tooling identity:** GEPA and Optimize Anything are presented as released, usable products with modes ("three optimization modes" — single problem, multitask search, skill building) and a named feature ("a feature called GSkill").
- **Anticipated-objection structure:** the speaker scripts Q&A style rebuttals ("The question is, but why keep a parto pool?", "Some people have asked me that oh as models get better..."), suggesting an audience that engages critically with the method.
## Observable Presentation Patterns (demonstrated, not claimed)
- Heavy use of **quantified before/after benchmarks** as persuasion (4.25% → 30.52%; 32.5% → 89.5%; 24% → 93%).
- **Concrete named-model comparisons** (GPT 4.1 mini vs. GPT 4.1, Qwen 38B self-optimizing, Claude Opus vs. tuned GPT OSS 120B) rather than abstract claims.
- One explicitly **playful segment** ("Let's say you were tasked with generating a 3D unicorn... This just for fun") indicating the channel tolerates lighthearted demos within technical content.
- Closing **philosophical framing** to the audience: "don't be afraid to optimize in the tech space and many problems can be framed as optimization."
## Self-Check
All observations trace to quoted or precisely described transcript passages. No channel-wide conclusions were drawn from a single video, no metadata was invented, and creator performance claims are labeled as claims rather than verified facts.
# Delivery Observations — Lakshya A. Agrawal, "Beating RL With Reflection: GEPA and Optimize Anything"
## Overall Communication Style
The delivery is a fast-paced, results-driven technical talk. The speaker moves quickly from problem framing → core idea → benchmarks → applications → adoption evidence, and frequently anchors claims in **quantified gains** ("7x to 30.52%", "90x cost reduction", "from 32.5% to 89.5%").
---
## Tone
- **Confident and promotional in places.** Claims are often stated at maximum strength:
> "The API is dead simple to use."
> "This entire process is fully automated now with Japa."
- **Persuasive rebuttals to anticipated skepticism.** The speaker pre-empts objections and argues against them directly:
> "Some people have asked me that oh as models get better the importance of prompt optimization will go down. I argue the opposite…"
- **Conversational asides.** Occasional informal register:
> "This just for fun." (the 3D unicorn example)
> "So please go and check it out. Thank you very much."
---
## Recurring Vocabulary and Phrases
Several terms repeat across the talk and function as its conceptual spine:
- **"Reflective optimization"** — the framing term from the opening: "the problem of reflective optimization or how can we self-improve prompts agents and models from textual feedback."
- **"Domain specific"** — appears constantly: "domain specific knowledge resources", "domain specific feedback", "domain specific information", "domain specific side information."
- **"Rollouts"** — used repeatedly when contrasting with RL: "hundreds of thousands of rollouts", "25,000 rollouts."
- **"Parto / Pareto pool"** — the candidate-selection mechanism is mentioned many times ("keeps a parto pool", "parto based candidate selection strategy").
- **"Actionable side information"** — a coined term repeated when describing the evaluator API.
- **Repetition for emphasis** — the speaker restates key claims immediately in varied form:
> "So, and Japa also improves multimodel VLM models performance."
> "more importantly… but more importantly…" (used at least twice as a pivot to a second benefit).
---
## Teaching Habits
- **Anticipated-question structure.** The talk is organized around questions the audience might ask, explicitly signposted:
> "The question we start with is how can we teach AI to perform new tasks."
> "The question is, but why keep a parto pool?"
> "Then the question we get asked is like can we actually use this…"
> "Some people have this question of uh what if we have subjective tasks…"
- **Concrete one-word examples to explain abstractions.** The 1-line vs 10-line summary prompt:
> "we can all agree that the behavior of the system would change quite significantly with that just one word change."
- **Guided chart reading.** When presenting results, the speaker walks axes explicitly:
> "On the x-axis we have the number of training steps… on the y-axis we have the performance on our domain."
- **Named credentials for external validation.** Repeatedly cites third parties to establish credibility: AMD/NPU XDNA2, Snorkel, Databricks, Dropbox and Shopify CEOs, OpenAI's blog post, "externally validated report."
- **Call to action with runnable artifact:**
> "This is a runnable example. You can go to this QR code and you can run this example right now."
---
## Communication Patterns
- **Rule-of-thumb framing near the close**, delivered as imperative advice:
> "don't be afraid to optimize in the tech space and many problems can be framed as optimization. So bring actionable side information and surface as much domain specific information as you can."
- **Generality claims via a simple test:** "If you can write it as text and score it, JPA can optimize it."
- **Escalating application ladder:** prompts → agent harnesses → code → numeric/cloud scheduling → skills, each presented as "the same thing can be applied to…"
- **Direct model-name comparisons** as proof points: optimizing GPT-4.1 mini to outperform GPT-4.1; GPT-OSS-120B tuned to outperform Claude Opus.
---
## Disfluencies and Verbal Tics
- **Product name pronounced inconsistently** across the transcript ("JPEA", "Japa", "Jeppo", "Jeppa", "JPA", "GEPA") — the transcript likely reflects unclear or shifting articulation; treat spelling variants as transcription artifacts rather than a deliberate pattern.
- **Filled pauses and restarts** appear regularly, especially mid-list:
> "uh very slow or expensive to do or the task metric is very slow"
> "uh uh like approach of discovering agent harnesses"
- **Trailing emphasis word** "itself" used repeatedly for reinforcement: "further increases that gap itself by another 2x", "It simply runs your systems", "the agent itself."
---
## Stable Patterns vs. Isolated Moments
**Stable (repeated across the talk):**
- Quantified before/after results as the primary evidence mode.
- Anticipated-question framing.
- "Domain specific" as a recurring value argument.
- Third-party validation citations.
**Isolated (thin evidence, do not generalize):**
- The humorous unicorn aside ("This just for fun") appears only once.
- The direct audience-imperative closing style occurs only in the final minute.
- The self-deprecating budget note ("we were very budget constrainted") is a single mention.
**Uncertainty note:** tone classifications rest on a single ~21-minute talk; whether the confident, objection-rebutting style is characteristic or specific to this venue cannot be established from one sample.
# Video Observation: Beating RL With Reflection — GEPA and Optimize Anything
**Speaker:** Lakshya A. Agrawal (presenting on behalf of a large collaborative effort)
## Core Problem Framing
### Sample inefficiency of standard training
- Agrawal argues that teaching AI new tasks traditionally requires **weight updates via gradient descent** (pre-training, SFT, RL), which demands enormous data: "trillions of tokens for pre-training, tens of thousands of labeled examples for supervised fine-tuning or hundreds of thousands of rollouts for reinforcement learning."
- He claims most teams lack such data/compute and that current AI problems are **"bottlenecked by sample efficiency"** for two stated reasons:
- **Low availability of domain-specific knowledge resources**, limiting offline methods like SFT.
- **Expensive rollouts** — either slow/costly agentic workflows or slow/costly task metrics (e.g., agents working for hours would make online learning with "hundreds of thousands of rollouts" infeasible).
### Critique of RL with verifiable rewards
- He argues that in the **RLVR paradigm** (parallel rollouts → rewards → GRPO-style gradient updates), the process compresses each rollout to an "O of one score," discarding rich information: chains of thought, tool calls, environment responses, and diagnostic error messages.
- Framed as a question: *"Can we make use of this other extremely rich information."*
## Core Idea: Reflective Optimization in Text Space
Two stated key ideas:
1. **Reflection over traces** — an LLM/agent inspects the full rollout trace to identify what worked and what didn't, potentially using intermediate outputs and additional tool calls (e.g., retrieval from internal knowledge bases).
2. **Prompt updates instead of weight deltas** — a single natural-language edit can cause large behavior change. His example: changing "generate a one-line summary" to "generate a 10-line summary" vs. "thousands of gradient... very tiny gradient updates" for a similar behavior shift.
## GEPA Claims
### Sample efficiency vs. GRPO
- Agrawal claims that with **Qwen 3 8B optimizing itself** ("no external expert teacher involved whatsoever"), GEPA in **one reflection round using three data points** achieved roughly **2x the performance gains GRPO got after 25,000 rollouts**, with further running widening the gap by another 2x.
### Quality of learned prompts
- He contrasts GEPA with prior prompt optimizers that exploit model idiosyncrasies (citing the "my grandmother will be really angry" style trick), claiming GEPA instead produces **detailed problem specifications** — how to interpret inputs, purpose/context, and key observations from data.
- Example given: a multi-hop QA second-hop retrieval prompt where GEPA discovered that first-hop documents cover one entity/aspect and second-hop retrieval should target related documents.
- He claims this automates what human engineering teams spend **weeks** doing manually per new model, with GEPA runs taking **"about half an hour to 1 hour."**
### Application examples
- **Proprietary models:** GPT-4.1 mini optimized to outperform GPT-4.1 on a math task.
- **AMD NPU XDNA2:** a new hardware API with "almost zero available information on the internet" caused GPT-4-era models to fail. An agent at 4.25% was pushed to **30.52% (7x)** with no agent changes. He highlights that GEPA discovered the instruction "avoid including adf.h" even though AMD ships an `adf.h` library — it simply didn't work with the newest hardware generation.
## Algorithm and Pareto-Based Selection
- Described as "extremely simple":
1. Run the pipeline on a few examples, collecting **domain-specific feedback** (anything the environment exposes).
2. **Reflection** — an LLM/agent reads feedback and proposes a better prompt.
3. **Pareto pool** — retain every candidate that wins on even one training example, not just the top scorer.
### Why a Pareto pool (addressed objection)
- He reports being repeatedly asked whether GEPA is better than "running the model in a loop." Their test: the loop approach **keeps only the best and gets stuck in local optima** (illustrated with a search tree that exhausted its budget), while Pareto-based selection yields a more balanced search and higher final score.
- Claim: across four benchmarks, **more than half of GEPA's gains** come from Pareto-based selection, yielding nearly **2x** the gains of a plain loop.
- Benchmark results claimed: **+10%** on question answering, instruction following, claim verification, and math — even though frontier models are heavily optimized for math already.
## Optimize Anything
- **Claim:** "If you can write it as text and score it, GEPA can optimize it" — prompts, agent harnesses (Python/JS files), CUDA kernels, serialized numeric parameters, cloud scheduling policies.
- **API design:** provide a set of problems plus a **fitness function** returning a score and an open-ended dictionary of "actionable side information" (compiler errors, profiler output, expert feedback, documentation, job traces, SLA violations).
### Stated applications and results
- **3D unicorn generation** (framed as "just for fun"): optimized Python script produced a better rendering than Claude Opus 4.6's direct attempt — noted as informal.
- **ARC-AGI agent discovery:** starting from a four-line chain-of-thought program, **16 rounds of reflection** produced a six-step agent (hypothesis induction, code synthesis, execution/tracing, automatic debugging, iteration) raising Gemini Flash accuracy from **32.5% to 89.5%**. Presented as runnable via QR code.
- **MATH-500:** GPT-4.1 nano accuracy raised by **20%** via an automatically discovered two-step agent.
- **Agent skills (GSkill):** a budget-constrained GPT-5 mini mini-SWE-agent went from **24% to 93%** (~3x) on Go repository issue resolution; those skills transferred to Claude Sonnet 4.5, reaching **100% issue resolution** while cutting execution time and tokens by roughly **half**.
- **Three optimization modes:** single-problem, **multitask search** (related problems with information transfer), and **skill building** for generalization to new deployment problems.
- **Cloud scheduling policy optimization:** ~**40% cost reduction** vs. expert heuristics.
- **Custom solvers:** claimed to match and exceed Optuna in black-box mathematical optimization.
## External Validation Claims
- **Snorkel:** employees improved internal benchmarks within 20 hours of release (per Agrawal, referencing their tweets).
- **OCR:** ~**35%** error reduction for leading VLMs — described as "an externally validated report."
- **Databricks:** **90x cost reduction** — tuned GPT-OSS 120B to outperform Claude Opus, with the performance delta over Opus larger than on open-source models.
## Stated Objections and Counterarguments
### "Won't prompt optimization matter less as models improve?"
- Agrawal explicitly argues **the opposite**: better models follow instructions better, so *more precise* task instructions yield *more* benefit — citing the Databricks result where Claude Opus "jumped much higher" with the better instruction.
### "What about subjective, hard-to-evaluate tasks?"
- Proposed solution: a **data flywheel** — collect production traces, have humans annotate ~50 trajectories with detailed feedback, use GEPA to optimize an **LLM-as-judge prompt**, then use that judge to optimize and deploy the agent, iterating. He states this is "a successful paradigm that... leading teams in production are already using."
## Related and Future Work
- **"Learning Fast and Slow":** co-optimizing model **weights and prompt harnesses**, claimed to show "very strong properties" desirable in continual learning — with the caveat "I don't have much time to go over details."
- **Adoption claims:** production use by named companies, CEOs of Dropbox and Shopify discussing use, and an OpenAI blog post on building self-improving AI systems with GEPA (as stated by the speaker).
- GEPA described as framework-agnostic, model-agnostic, with "absolutely zero hard dependencies" and open source.
## Concluding Exhortations
- *"Don't be afraid to optimize in the text space."*
- *"Many problems can be framed as optimization."*
- Surface as much domain-specific, actionable side information as possible — "the optimizers of future will be able to work with them."
## Unverified / Tentative Elements Preserved
- All performance figures are as stated by the speaker; no independent verification is available in the transcript.
- The unicorn example is explicitly labeled by the speaker as "just for fun."
- The "learning fast and slow" results are explicitly deferred and not detailed in the talk.
- External reports (Snorkel, OCR, Databricks, executive endorsements) are relayed claims, not demonstrated in the talk itself.
# Speaker & Provenance Record
## Video Identification
- **Title:** *Beating RL With Reflection: GEPA and Optimize Anything — Lakshya A. Agrawal, GEPA*
- **Video ID:** `01a15ca7-2a6f-7bd3-b980-528973dac9ab`
## Speakers & Roles
| Speaker | Role | Basis |
|---|---|---|
| **Lakshya A. Agrawal** (transcript self-rendered as "Lakshia Agraal"; title spelling treated as authoritative) | **Presenter / creator-side speaker**, presenting "on behalf of a very large effort" | First-person introduction: *"Hi everyone, my name is Lakshya Agraal and today I'll be presenting on behalf of a very large effort"* |
- **Single-speaker talk.** No guests, interviewers, narrators, or other voices appear in the transcript.
- No curated metadata beyond the title was supplied; speaker affiliation (e.g., institutional role beyond presenting the work) is **not established** by the source.
## Named Work & Projects Referenced (as claimed by the speaker)
- **GEPA** — reflective prompt optimization technique for agents; described as open source with a repository.
- **Optimize Anything** — universal API for optimizing any text parameter; three modes: single-problem, multitask search, and skill/generalization mode.
- **GSkill** — skill-optimization feature, described as located "in the GEPA repository" and "fully open source."
- **"Learning Fast and Slow"** — paper on co-optimizing model weights and prompt harnesses (referred to, not detailed).
- Related methods mentioned for comparison: **GRPO** (RL technique), prior prompt optimizers, **DSPy-adjacent** context not explicitly named (not recorded as fact).
## Third-Party Claims & Attributions (speaker's assertions — provenance only, not verified)
- **AMD NPU XDNA2** case: agent improved from 4.25% to 30.52% using GEPA.
- **Quen 38B** (transcript rendering; likely Qwen) self-optimizing claim — "no external expert teacher."
- **Proprietary model results:** GPT 4.1 mini optimized to outperform GPT 4.1 (math); GPT 4.1 nano +20% on MATH 500 (transcript renders "math 500").
- **RKGI task:** Gemini flash 32.5% → 89.5% within 16 reflection rounds.
- **MiniSWE agent / GPT5 mini:** 24% → 93% on Go repository issue resolution; skills transferred to "Claude Sonnet 4.5" reaching 100% with ~50% time reduction.
- **Snorkel:** internal benchmark improvements within 20 hours of release (speaker cites tweets).
- **OCR/VLM:** ~35% OCR error reduction described as "an externally validated report" (no named source given).
- **Databricks:** claimed 90x cost reduction; GPT OSS 120B tuned to outperform Claude Opus.
- **Cloud scheduling policy:** ~40% cost reduction vs. expert heuristics.
- **Executives cited:** CEO of Dropbox and CEO of Shopify "talking about their use of GEPA."
- **OpenAI:** blog post on "building self-improving AI systems with GEPA" (referenced, no link/date given).
## Promotional Indicators
- ⚠️ The talk functions substantially as **product/method promotion**: calls to action ("please go and check it out"), QR code to a runnable example, open-source repository pointers, and third-party adoption testimonials. Flag for downstream use as vendor-originated material.
## Availability & Evidence Channels
- **Comment availability:** Not determinable from the source material.
- **Papers/repositories:** Referenced but no URLs, DOIs, or timestamps provided.
- **External validation:** One claim explicitly labeled "externally validated" (OCR results) but the validating party is unnamed.
## Self-Check Notes
- All named entities, benchmarks, and third parties above appear explicitly in the transcript.
- Transcript contains ASR-name uncertainties ("Lakshia Agraal," "Quen 38B," "parto/parto pool" = Pareto, "JPEA/Japa/Jeppa/GEPA" variants); title used for canonical naming.
- No content-quality judgments recorded.
Hi everyone, my name is Lakshia Agraal and today I'll be presenting on behalf of a very large effort uh the problem of reflective optimization or how can we
self-improve prompts agents and models from textual feedback. The question we start with is how can we teach AI to perform new tasks. The standard way has
been to perform weight updates with gradient descent either during pre-training, supervised fine-tuning or reinforcement learning. This has proven to be extremely effective, but it
requires a huge number of examples. trillions of tokens for pre-training, tens of thousands of labeled examples for supervised fine-tuning or hundreds of thousands of rollouts for reinforcement learning in domains like math, coding, etc. However, most teams do not actually have that much data or compute and in fact
the problems are that we are trying to tackle with AI now are bottlenecked by sample efficiency. What do we mean by that? Two things. First of all, there is
low availability of domain specific knowledge resources which means there is not enough data to perform offline algorithms like SFT. Second, the domains that we are trying to apply AI increasingly are having expensive rollouts where either the LLM workflow pipeline or agentic rollouts are itself uh very slow or expensive to do or the task metric is very slow or expensive to execute. We are seeing that agents can now work for hours on end and if you were to apply an online learning algorithm to this uh it would require hundreds of thousands of rollouts and it would not be feasible. So we are seeing increasing use of agents for real world product uh applications where uh these invoke tools which can also be long running further exacerbating the sample inefficiency issue. The current dominant paradigm is reinforcement learning with verified rewards where given a model and a task,
we perform any number of parallel rollouts and get rewards at the end. Finally, an algorithm like GRPO takes these rewards and converts it into gradients that are applied back to the
model. However, as we can see, there was a lot of information in each of these rollouts, but we only learned an O of one score and propagated that via gradient descent. We can see that there is chains of thought, the tool calls made to the environment, the envir environment's responses to those tool calls, which could potentially contain error messages which also provide diagnostic value and we learned almost nothing from all of that. So the question we ask is can we make use of this other extremely rich information.
Our idea is to perform reflective optimization in text space where instead of only using the zero or one reward signal, we can have a language model or
an agent look at the trace of the entire rollout and reflect on what worked in them, what did not work in them. And this reflection could potentially use all intermediate outputs and potentially even make other tool calls such as retrieval from your company's knowledge base or some guide textbook and so on. So that's the first key idea and the second is that instead of only updating weights with small deltas, we can instead update a prompt where a single natural language update can give a very large behavior change. Let's take a simple example. Let's say you're tasked with writing a text summarization system and the prompt of that system says generate a oneline summary. If I just go and tweak that prompt to say generate a 10-line summary, we can all agree that the behavior of the system would change quite significantly with that just one word change. And making that one word change is quite quick and we can reflect on our own behavior and identify what needs to change. If we were to achieve a similar kind of behavior update from our AI system, we would have to have thousands of gradient very tiny gradient updates sequentially. So with that key idea, we proposed JPEA which is a reflective prompt
optimization technique for agents. It uses an evolutionary loop along with a novel parto-based candidate selection which I will come to later. It is akin to doing reinforcement learning in text
space where instead of just rewarding receiving a reward score we are actually obtaining score along with textual feedback which can be very domain specific and learn all about the domain
from it. Let's compare Japa with gRPO which is one of the leading RL techniques. On the x-axis we have the number of training steps uh also proportional to number of
data samples seen and on the y-axis we have the performance on our domain that we are training for. And what we can see is that Japa in just one round of reflection using just three data points is already able to get twice the performance gains that gpo got after 25,000 rollouts. Continuing to run Japa for a few more steps further increases that gap itself by another 2x. I want to note here that the model Quen 38B is optimizing itself here. There is no external expert teacher involved whatsoever. And what does Japa learn? Unlike prior prompt optimizers somewhat which would
uh uh use model idiosyncrasies like my grandmother will be really angry if you don't generate a good prompt. Here Jpa is actually giving a very detailed
problem specification which includes how to make sense of the input. What is the purpose and context of this particular pip part of the pipeline? What are some key observations and lessons from the data? So the prompt we are seeing here is for the second hop of a multihop question answering system where given a question we need to retrieve some documents that could potentially answer that question. Look at those documents summarize it and then finally answer the question. And here what we see is Japa has found out that first hop documents that often cover one entity or aspect and the second hop should actually be uh recovering documents that are related to it. We have seen that human engineering teams whenever a new model comes out spend weeks of their time manually tweaking one word here and there trying to discover the problem specification. This entire process is fully automated now with Japa which takes about half an hour to 1 hour to run depending on your uh pipelines. We can also apply Japa to leading proprietary models. Just for an example
here we were able to optimize GPT 4.1 minis performance to outperform GPT 4.1 on a math task and we can see the kind of information distillation JPA has done
in the prompt space itself. Coming back to the problem of sample efficiency, AMD developed a new hardware accelerator called NPU XDNA2 which had used a
completely new API to program which had almost zero available information over on the internet and because of this uh the leading models at the time which was GPT4 was failing miserably to perform
this task. We are able to take an existing agent which was getting 4.25% 25% on this task and apply Japa without any other change to the agent itself and we got this prompt and pushed this performance 7x to 30.52%. So what this is uh what this goes to say is there can be lots of domain specific information which if you include in your AI systems prompts the models could actually perform much better and JPA can help you fully automatically discover that. I want to highlight the sentence saying avoid including ADF.h H. Now the interesting thing is AMD actually ships a library called ADF.h for programming NPUs but that did not work with this latest uh generation of hardware that we were working with and Jeppo was able to discover that in just one step. So how does it work? It's an extremely simple algorithm which simply takes your AI pipeline written in any agentic framework or even raw LLM calls that you
may have. It simply runs your systems on a few examples and collects domain specific feedback. whatever information your environment contains is observed. Second, it runs reflection with an LLM
or agent that reads the feedback and proposes a better prompt. Finally, and most importantly, it keeps a parto pool where it keeps every single candidate that wins on even one training example and not just the top scorer. The question is, but why keep a parto pool? And we kept getting asked this question a lot that is Jepper really better than
running the model in a loop. So we went and tested it out and what happens is a loop keeps only the best and gets stuck in a local optima. So on the left hand side you see a search tree that was
generated by using an LLM in a loop starting from a seed prompt at the top left where um we asked the LLM to improve the prompt. It improved the prompt and it generated a prompt that gave us the middle node. However, this prompt got stuck in a local optima and once again when we asked the LLM to try and improve it, it proposed something but that was not actually better. So, it went back and it again tried to improve it and it kept doing this and it exhausted all of the search budget. On the other hand, with Japa's parto based candidate selection strategy on the right, we can see that it maintains a much more balanced search process eventually converging to a much higher score. Across four benchmarks, we saw that more than half of the gains seen with Japa actually account for this and it gets almost twice the performance gains that you would get with just applying the model in a loop. Japa can perform really well across diverse benchmarks. Here we see results
on question answering, instruction following, claim verification as well as math which all the leading frontier model companies are already optimizing their models a lot for and we are still able to get plus 10% just by optimizing
the prompt on it. So we have so far seen Japa only optimizing the prompts but Japa goes far beyond prompts. And because prompts are just text artifacts
that determine AI system behavior, the same algorithm can improve anything that you can express as a piece of text and you can score. For example, your entire
agent harness is eventually just a Python or a JavaScript file and we can apply the same kind of reflective optimization process to that entire file and we can work with it. So if you can write it as text and score it, JPA can optimize it. So with that insight in mind, we propose optimize anything which is a universal API for optimizing any text parameter given any domain like code optimization where let's say you want to optimize the CUDA kernel code. The input is just that CUDA kernel code where an evaluator looks at this piece of code, maybe compiles it, profiles it, generates a bunch of related information that we call as actionable side information which is then provided to an LLM which proposes an better candidate maintaining this parto and it keeps the uh repeating this process um till we get convergence. The same thing can be applied to numeric optimization where your numbers can actually be serialized as text or harness optimization where an entire harness can be serialized as text or even cloud scheduling policy optimization where the scheduling policy or heristic algorithm can be expressed as a piece of text and the evaluator can be something like the negative of cost or some function measuring accuracy uh efficiency and the actionable side information can be something like job traces SLA violations and so on. The API is dead simple to use. All it requires is you give us the set of
problems that you care to be solved along with an evaluator function or a fitness function that returns a score along with any available domain specific side information. If your domain
produces expert feedback, return that. If your domain produces compiler error messages, profiler messages, tool call error messages, return that. If you have maybe a written up documentation, return that. any kind of it's a very open-ended dictionary. You can return literally anything and all you do is you call optimize anything with this fitness function and the set of problems that you have and optimize anything will sort of take care of it um and give you a optimized solution. Let's see some applications. Let's say you were tasked with generating a 3D unicorn. This is
all the code that you would write or your agent can now write it because we have seen that optimize anything is a very easy to use API for leading agents like plot code. So all you do is write
this code which says optimize a Python program to generate a 3D unicorn. Um and the candidate is a Python script that produces a PNG rendering whatever and here is the result. On the left hand side we can see claude opus 4.6. If you gave it this task, this is what it generated. And on the right hand side, what what we the unicorn that we get with optimize anything. This just for fun. But let's say you were tasked with writing an agent to solve a specific task. Typically teams spend lots and lots of time tweaking their agents,
building tools for it, writing tool descriptions, uh carefully orchestrating the control flow and so on. Here we started with a simple four-line Python program that was simply calling a
model's uh chain of thought to solve an RKGI problem. Within just 16 rounds of reflection, JEPA within optimize anything was able to find this sophisticated sixstep agent that took RKGI accuracy on RKGI uh that took RKGI accuracy of Gemini flash from 32.5% to 89.5%. And we can see that this agent is automatic like by itself doing rule hypothesis induction code synthesis. It executes and traces the code automatically debugs this code goes back and proposes new versions of that code. And finally it runs it on the actual test inputs and returns the output. This is a runnable example. You can go to this QR code and you can run this example right now. So um applying the same uh uh like approach of discovering agent harnesses to math 500 we are able to push its
accuracy of GPT 4.1 nano by 20% by simply creating a two-step agent and again I want to emphasize that all we did is we asked optimize anything to
optimize an agent file and it was automatically discovering the sophisticated agent architecture and we did not have to do anything other than specifying the objective and the task.
Finally, every single one of us is using uh some coding agent like cloud code or codex or maybe your favorite agent and agent skills has become a very leading
part of the ecosystem where almost all coding agents understand skills. Let's say you want to optimize skills for your specific repository. This is the code that you write which says learn a skill from the trajectory. When the coding agent is presented with similar problem, the skill should be helpful. We just gave it this natural language behavior. And what we see is we started with minisu agent with GPT5 mini because we were very budget constrainted and we were able to take its performance from 24% to 93%. An almost 3x jump on go repository issue resolution but more importantly the skills that were optimized very cheaply on a GPT5 mini agent we are able to take that and apply to the latest claude sonnet. This was done of uh about a few months back but we applied it to clots onet 4.5 pushing its accuracy to 100% issue resolution while more importantly cutting down the execution time or issue resolution time by almost 50%. We cut it down into half which also means it spent less tokens because skills contain information about how the repository is organized, how to invoke the test cases, where a particular feature is implemented, um what are the build system used by this repository and so on. This is a a feature called GSkill. You can find it in the JPA repository and it's fully
open source as well. So, optimize anything is a single uh interface that provides three optimization modes. If you have just a single problem like there is a single matrix multiplication kernel that you want to optimize you can
use it that way. If you have any number of related problems like you want to optimize a matrix multiplication kernel along with a dot product kernel and you know there might be some information transfer between these two you can use what we call as the multitask search mode and finally build a skill which is if you want to optimize on a set number of problems but your uh deployment can actually come up with many new problems. So like uh in case of math op like in case of math prompt optimization we are training on some examples but when we deploy it we can receive a completely new kind of query. So we care about generalization mode. So there you can do prompt optimization agent architecture optimization and so on. So optimize anything is can be used for a broad set of domains including cloud
scheduling policy optimization where we were able to cut costs by almost 40% compared to expert huristics write custom solvers to match and exceed Optina even in blackbox mathematical
optimization create agent skills prompt optimization and so on. It is so easy to use that within just 20 hours of releasing it, people at Snorkel had already improved some of their internal benchmarks with it and were tweeting about it. So, and Japa also improves multimodel VLM models performance. Here we are able to cut OCR error rates for leading models by almost 35%. And this is an externally validated report. Um, similar similarly, data bricks actually achieved 90x cost reduction in their deployed agents performance. uh uh performance and here they were able to tune GPT OSS 120B to outperform Claude Opus while being 90x cheaper. More importantly, the performance delta improvement that you see on top of Claude Opus is actually bigger than the one you see on open source models. Some people have asked me that oh as models
get better the importance of prompt optimization will go down. I argue the opposite which is as models get better they will get better at instruction following and the more precise
instruction about your task that you have to give to a very smart model the better that model will be at a uh solving your task and this is exactly what we see happening here the better the instruction was claopus actually jumped much uh higher some people have this question of uh what if we have subjective tasks which are very hard to evaluate jpa can
actually learn evals for your task from production traces. The way to do that is you collect a bunch of production traces from your agent. Get a human to annotate just about 50 of those trajectories
giving very detailed feedback. This is a long response. This is a short response. This is a good response. This uses this terminology, whatever. And once you get those human annotations, you can use JPA to optimize an LLM as a judge prompt. And you can use that LLM as a judge prompt then to go back and optimize your agent and deploy that agent. And this becomes a data flywheel where you can keep improving it. And this is a successful paradigm that uh some leading teams in production are already using. Then the question we get asked is like can we actually use this uh reflective
optimization to train models and we recently had this paper called learning fast and slow where we propose fast slow learning where we can co-optimize model weights and prompt harnesses and this
shows some very strong properties that one would want in a continual learning algorithm. Um I don't have much time to go over details but please uh look at the uh papers and uh since uh since release Japa has been used in production by these companies as well as the main methodology in these papers and here the CEO of Dropbox and
Shopify are talking about their use of Japa and OpenAI also wrote a blog post about how you can build self-improving AI systems with Japa. Um so it's very simple to get started. It can plug into
any framework, any model and it has absolutely zero hard dependencies. So you can deploy it any in any kind of setting. So um don't be afraid to
optimize in the tech space and many problems can be framed as optimization. So bring actionable side information and surface as much domain specific information as you can to optimizers and
the optimizers of future will be able to work with them. So please go and check it out. Thank you very much.