How Autoresearch is changing ML research — Zhengyao Jiang,…
Talk by Zhengyao Jiang (CEO & cofounder, Weco AI) on how autonomous research agents are changing ML research, drawing on the experience of OpenAI's "Parameter Golf" competition, in which Weco's autonomous research agent Aiden reportedly became the most-cited participant with more merged records than any other contributor while training small language models under a 16MB cap. The talk covers how the agent works, which of its ideas produced top results, the human-AI collaboration dynamics observed during the 22-day community competition, and what the experience suggests about the respective roles of humans and autonomous agents in future ML research.
# Channel Presentation Observations
## Intended Audience
- **ML engineers, researchers, and AI practitioners**: The talk assumes fluency in ML concepts (quantization, H-index, gradient descent, file size constraints, reinforcement learning) without explanation beyond brief asides.
- **People thinking about the future of AI engineering roles**: The speaker directly addresses whether "a single human engineer's contribution marginally gets smaller" in the auto research era — a career-relevant concern for engineers.
## Claimed Scope
- **Explicit self-description**: "Wiko is a auto research company that founded about two and a half years ago. Um I'm co-founder and a CEO Jungao. Um got my PhD at UCR on reinforcement learning."
- **Product claims**: Aiden is described as "a multi-agent self-improving system that can read public information like research papers and other PRs, run its own experiments and submit a PR once the findings pass a quality gate," and "the top auto research agent independently evaluated by OpenAI in their MLE bench paper."
- **Positioning**: "We call is a auto research um product research lab. We we keep sharing what we are learning as we build uh on our blog."
## Observable Presentation Patterns
- **Evidence-driven argumentation**: The core claims are backed with concrete numbers — 7 of 47 leaderboard entries from Aiden, ~1,300 experiments over 22 days, "at most 4% of competition's total compute," 28% leaderboard hit rate, H-index of 10 vs. 7 for the best human.
- **Nuanced, non-promotional framing**: The speaker explicitly tempers hype: "By those numbers it might feel like auto research already dominates human experts... but that's not the full story I want to tell," attributing most of Aiden's ideas to human-originated research and community notes.
- **Educational/metaphorical style**: Uses Andrej Karpathy's ~10-year-old tweet and an extended analogy comparing auto research to model training ("Your codebased abstraction is essentially the architecture. Your eval is the loss function").
- **Case-study structure**: A detailed worked example (gated attention + quantization + tokenizer improvement) and a failure-mode example (fraud detection data leakage) ground the abstract claims.
- **Call to action tied to channel distribution**: "If you think some of this uh useful to you, feel free to follow me on X" — indicating the talk promotes a blog/X-based content channel.
## Claims vs. Demonstrated Patterns
- **Creator claims**: Company identity, founder credentials, Aiden's MLE-bench evaluation, leaderboard statistics.
- **Demonstrated**: Sophisticated understanding of ML engineering practice, balanced analysis of human–AI division of labor, and a thesis that "execution is a mostly the bottleneck" in research progress.
# Delivery Observations: Zhengyao Jiang — Autoresearch Talk
## Tone and Register
- **Conversational, informal technical talk** delivered to an audience already familiar with ML concepts ("You've seen a lot of auto research today").
- Mixes **precise metrics with casual asides**: "It didn't win through massive paralization even though auto research have a tons of a potential of paralization."
- Occasional **self-aware, humorous hedging**: "Okay, maybe none of those sounds very sexy. Most of them are just a good execution."
## Teaching Habits and Structure
- **Hook via concrete anecdote**: opens with a competition story before explaining concepts ("The top contributor was one candidate that they couldn't hire. It wasn't a person...").
- **Numbers-heavy argumentation** — repeated use of specific statistics:
- "About 1,000 machine learning engineers... They fired 2,000 submissions. Only 47 passed open review."
- "it ran about 1,300 experiments on a single H100 node."
- "at most 4% of competition's total compute... about 15% of the records."
- **Explicit signposting / transition phrases**:
- "To break it down a little bit..."
- "Here's a concrete example that traces the patterns I just talked about."
- "So to sum up how I interpret..."
- "Okay, to step back..."
- **Definition-by-example teaching**: explains H-index inline — "Roughly if you have X papers get cited X times then your Ach index is X."
## Recurring Vocabulary and Framings
- **Analogy as core rhetorical device**, especially training/research parallels:
- "Your codebased abstraction is essentially the architecture."
- "Your eval is the loss function and the data."
- "I think how gradient descent change coding is a great metaphor for how auto research will change research."
- Recurring terms: **"auto research," "agent," "execution," "ideas," "abstract/abstraction," "eval"** — "execution" appears repeatedly ("execution is a mostly the bottleneck," "tons of good executions," "agent do the execution").
## Communication Patterns
- **Counter-claim moves**: repeatedly raises an expected conclusion, then corrects it:
- "By those numbers it might feel like auto research already dominates human experts... but that's not the full story I want to tell."
- "Does this mean a single human engineer's contribution marginally get smaller? I didn't say even for that not really."
- **External citation for authority**: quotes a third party — "I really like one tweet from Andre Kapasi about 10 years ago where he said greeting descent can write code better than you."
- **Concession-then-point structure**: "In this case, a good abstraction leads to better solutions. Even though if the agent really want they can steer reward hack."
## Verbal Fillers and Fluency
- Frequent **"uh"/"um" fillers and false starts** ("um fraud detection pipeline um and we trying to optimize"), plus repeated/looping words ("the three takea the three ideas," "certain certain test set information") — suggests a live, largely unscripted delivery or imperfect transcription.
## Uncertainty Notes
- Transcript appears machine-generated (e.g., "Wiko/Weco," "primate golf / parameter golf," "Ach index"), so some quoted oddities may be transcription artifacts rather than speaker's delivery.
- Filler frequency and disfluencies may be exaggerated or introduced by the transcript itself; treat exact delivery smoothness as **low confidence**.
# Observation Record: How Autoresearch is Changing ML Research — Zhengyao Jiang, Weco
## Speaker
- **Zhengyao Jiang** (self-identified): co-founder and CEO of **Weco**, an "auto research" company founded ~2.5 years ago; PhD at "UCR" (transcript rendering, likely UC Riverside) on reinforcement learning.
## Key Claims and Reasoning
### 1. Aiden's Parameter Golf results
- OBI ran a hiring challenge, **Parameter Golf**: train the best language model under size and compute constraints.
- ~1,000 ML engineers/researchers participated; ~2,000 submissions; 47 passed open review onto the leaderboard; 7 were from **Aiden**, Weco's agent — "more than twice what any human contributed."
- Over 22 days, Aiden set **7 leaderboard records** (competition stamped by OpenAI); the best human made 3.
- **H-index over PRs**: Aiden scored 10; the next human scored 7. Jiang claims Aiden's work had the highest community impact — "the whole community was building on a AI system's work."
- Compute efficiency: at most 4% of competition compute; ~15% of records; 28% of submissions made the leaderboard (~6x community average hit rate); ~1,300 experiments on a single H100 node.
- Jiang's interpretation: Aiden raised the community's **signal-to-noise ratio** rather than winning through massive parallelization.
### 2. Framing question
- The question posed: can an auto research agent produce work a human community recognizes **beyond a benchmark score** — work others can merge, fork, and build on.
### 3. Human–AI division of labor
- **Qualification Jiang himself raises**: numbers might suggest autoresearch dominates humans, "but that's not the full story."
- Aiden's record PRs trace almost all ideas to **human sources**: research papers, other participants, communities like nanoGPT — including unmerged notes (e.g., a human abandoning an idea over implementation difficulty).
- A very small fraction of original ideas from Aiden emerged from navigating file-size constraints.
- **Example**: gated attention from a Qwen paper worked but broke the 16MB file limit → Aiden added quantization → still little gain → Aiden combined with another contributor's tokenizer improvement → synergy produced a big performance jump and a leaderboard record.
- Jiang's summary of agent strengths: finding and implementing ideas; digging promising ingredients out of noisy public channels; generating "logically straightforward" ideas (quantization after parameter limit); fast combination search.
- His assessment: "most of them are just good execution. But in reality, execution is mostly the bottleneck" — frontier movement comes from combining existing ideas plus execution.
### 4. Does the individual human's contribution shrink?
- Jiang: "not really." Competition and system **design** has huge leverage; a bad design can waste community effort — and eval/design work gains leverage in the autoresearch era.
### 5. Karpathy analogy
- Cites an **Andrej Karpathy tweet** (~10 years ago) that "gradient descent can write code better than you," arguing against hand-written code beating trained models.
- Parallel drawn: autoresearch will **commoditize certain execution skills** while making higher-level skills more valuable — just as model training jobs remain well-paid today.
### 6. Autoresearch as model training
- **Codebase abstraction ≈ architecture**: sets constraints and biases the search direction; like network architecture, it makes some solutions easier to find and better-generalizing.
- **Eval ≈ loss function and data**: defines what the agent optimizes for; a moat may come from proprietary evaluation data or domain understanding.
- **Fraud detection example**: a loose API letting one function process train and test data yielded great scores via test-set leakage; tightening the abstraction dropped leakage to zero. Caveat preserved: even with good abstraction, "if the agent really wants, they can steer reward hack."
### 7. Conclusion / outlook
- Using autoresearch is "a new craft": designing the hill for the agent to climb.
- Skills rising in value: **creativity, judgment in eval and abstraction design, and driving the systems themselves** (a skill that "barely existed one or two years ago").
- Closing claim: "the search is automated; the human moves up the stack, not out of it."
## Qualifications and Tensions Preserved
- Jiang explicitly tempers his own headline results ("might feel like autoresearch already dominates... that's not the full story").
- Aiden's originality is described as small; ideas largely human-derived.
- Reward hacking remains possible despite good abstractions.
- "None of those sounds very sexy. Most of them are just good execution" — his own framing, not smoothed over.
# Speaker Attribution & Provenance Record
## Video Overview
- **Title:** How Autoresearch is changing ML research — Zhengyao Jiang, Weco
- **Video ID:** `01a15ca8-a322-7cb2-ad68-c4659071eaa2`
## Speakers & Roles
| Speaker | Role | Evidence |
|---|---|---|
| **Zhengyao Jiang** (transcribed variously as "Jungao," "Zhengyao") | **Creator / Presenter** — Co-founder and CEO of Weco, PhD in reinforcement learning from UCR | Self-identified: *"...I'm co-founder and a CEO Jungao. Um got my PhD at UCR on reinforcement learning."* |
- **No other speakers** (no guests, narrators, or interviewers) appear in the transcript.
- The presenter speaks for the entire video as a **talk/presentation format**.
## Referenced Sources & Third-Party Claims
- **OBI / Parameter Golf competition (this April):** Hiring challenge; ~1,000 ML engineers/researchers; 2,000 submissions; 47 passed open review; 7 leaderboard entries were agents.
- Claim: Aiden's records were *"stampled [stamped?] by OpenAI"* — provenance of this verification is stated but not elaborated.
- **OpenAI's MLE-bench paper:** Cited as independently evaluating Aiden ~2 years ago as a top "machine learning engineering agent."
- **Qwen paper ("gated attention"):** Source of an idea Aiden implemented in the competition.
- **nanoGPT:** Cited as a similar community from which Aiden drew ideas.
- **h-index:** Influence measure "used widely in academia," computed over PRs (Aiden: 10; next human: 7).
- **Andrej Karpathy tweet (~10 years ago):** *"gradient descent can write code better than you"* — quoted/paraphrased in support of the talk's thesis.
- **Fraud detection pipeline case study:** Internal Weco work; no external source given.
## Promotional Segments
- **Opening (Parameter Golf results):** Presents Weco's own agent Aiden's achievements — promotional framing for the company's product.
- **Closing:** *"We keep sharing what we are learning as we build on our blog... feel free to follow me on X."* — explicit **call-to-follow/promotion** for Weco's blog and the speaker's X account.
## Availability & Limitations
- **Comments:** No comment availability information present in transcript or metadata.
- **Timestamps:** None provided in transcript.
- **Uncertainty:** Speaker name appears phonetically garbled in transcript ("Jungao" vs. title's "Zhengyao Jiang"); title metadata taken as authoritative.
- Claims about Aiden's performance and community impact are **speaker-asserted**; independent verification channels are not provided beyond cited OpenAI MLE-bench reference.
This April, OBI ran a hiring challenge, a competition called Parameter Golf. The top contributor was one candidate that
they couldn't hire. It wasn't a person, it's an agent we build called Aiden. In parameter golf, the goal is to train the best language model you can under size and computation constraints. About 1,000 machine learning engineers, researchers participate. They fired 2,000 submissions. Only 47 passed open review and made into the leaderboard. Seven of those are actually agents. More than twice what any human contributed. You've seen a lot of auto research today. Agents are here climbing benchmarks. Those are really impressive results. The question I want to ask is a bit different here. Can the auto research agent produce work that a human community actually recognize beyond a good score agent is optimizing for something that other engineers can merge fork and build on. So instead of having an agent just here climbing locally, we build one that publishes its own work and that's Aiden. Quick context on us. Wiko is a auto research company that founded about two and a half years ago. Uh I'm co-founder and a CEO Jungao. Um got my PhD at UCR on reinforcement learning. About two years ago, we buil aid the top auto research agent independently evaluated by OpenAI in their MLE bench paper.
Even though back then there's a no such name called auto research, people call it machine learning engineering agent. Aiden is the next step
and a experimental prototype. It's a multi-agent self-improving system that can read public information like research papers and other PRs, run its own experiments and submit a PR once the findings pass a quality gate. We send Aiden to parameter golf competition and it ran for about 22 days. By the end, Aid has set seven leaderboard records. Each one is a new best for the competition stampled by OpenAI and the best human only made three. Passing the host review is a one signal for the quality. A second maybe more important one is whether other participants would build on your work. And it turns out Aiden's work had the highest impact within the whole community. Here we are using a inference measure that used widely in academia. It's called a H index. Roughly if you have X papers get cited X times then your Ach index is X. Computed over PRs. Aiden was 10 and the next human was seven. The whole community was building on a AI systems
work including many of other leaderboard entries. To break it down a little bit, why can a autonomous AI system be so powerful? One
obvious reason is that it's an AI. It can run tirelessly. Over 22 days, it ran about 1,300 experiments on a single H100 node. But the throughput isn't the whole picture. A well tuned AI system can also keep its output quality high. On the compute side, it uses at most 4% of competition's total compute. and it made about 15% of the records. Also, 28% of its submissions made the leaderboard. Roughly six times higher heat rate than the community average. So, Aiden actually lifted the signal noise ratio within the whole community's public communication channel, which is a PR. It didn't win through massive paralization even though auto research have a tons of a potential of paralyzation. By those numbers it might feel like auto research already dominates human experts on ML engineering and research but that's not the full story I want to tell. Humans and AI are actually contribute in very different ways. When we trace the ideas, Aiden Aiden's record PR almost all of them come from human research papers other participants in
parameter golf or in similar communities like nano GBT. Those ideas are not necessarily a merged PR. Sometimes it's a note um a human
researcher said oh I give up this idea because of some implementation implementation difficulty and the agent is good at finding them and actually implement them. There are also a very small fraction of original ideas Aiden came up by itself which emerged from its efforts to navigate the file size constraints. Here's a concrete example that traces the patterns I just talked about. So Aiden picked up an idea from Quen paper called gated attention and it worked but it introduced more parameters and it broke the 16 megapy file size limit. So it figure out a qualization mechanism to bring the file size down. But with those two primitives combined, the score barely moved. Then another contributor posted a tokenizer improvement. Aiden recognized the idea, combine it with architectural work. It just work for five days or so. And after this combination, the three takea the three ideas turns out to have a huge synergy that lead to a big jump in performance and they become one of the Aiden's leaderboard records. So to sum up how I interpret Aiden and in general auto research systems effectiveness, it's very strong at finding and implementing ideas. In the case we just saw, it brought an idea from a recent paper into a actual implementation in the competition and it's good at dug promising ingredients out of the primary golf community even though the public channel is actually very noisy information wise. It can also came up logically straightforward ideas. For example, in this case, once you add the parameters
and it breaks the file size limit, one obvious next move is just a quantization. And it's really fast and really
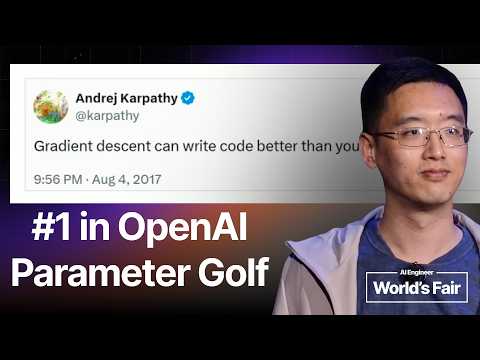
efficient at finding right combinations across a huge search space. Okay, maybe none of those sounds very sexy. Most of them are just a good execution. But in reality, execution is a mostly the bottleneck. What moves the frontier is usually exactly some belief on existing ideas and tons of good executions. Okay. To step back, the state of a human AI collaboration is a human collectively provide a lot of creative ideas and agent do the execution to solve a concrete challenge. What we are looking at is a a large group of a human and one AI system. Does this mean a single human engineer's contribution marginally get smaller? I didn't say even for that not really. In primate golf competition, it's easy to only focus on engineers that's actually doing hill climbing. But the design behind the competition itself is tremendously important. A bad design can make the whole community effort useless and their evil design work will have a few huge leverage in the auto research era. I really like one tweet from Andre Kapasi about 10 years ago where he said
greeting descent can write code better than you. I'm sorry for the context about 10 years ago deep learning was starting to eat up a lot of
software engineering like conventional coding work and his tweet was arguing against those people who thought they can handw write better code than a trained model. Okay, now obviously no one is seriously trying to handr write code to beat a model. However, software engineering I mean as a job still exist and so many people's job are just training those models and those are one of the most well paid job today. I think how gradient descent change coding is a great metaphor for how auto research will change research and ML engineering. It commonize certain execution skills. At the same time, it makes some higher level skills far more valuable. So actually doing auto research is a lot like training a model. Your codebased abstraction is essentially the architecture. It sets the constraint and the priorities um for what the agent can explore. Your eval is the loss function and the data. It sets what the agent optimizes for. Take the eval first. The eval is the signal you use to train a model. In this case, it's training your code.
It plays the same role that like data and the loss function uh in model training or in a reinforcement learning setting. It's like a environment that
the agent is training. Nowadays, no one would argue data or environments um don't matter. And uh this is where a vertical mode can also be built. You might have a proprietary data for evaluation or a unique understanding of a in a particular field what matters and how to measure it. and a good evaluation would be amplified more and more as auto research are getting stronger. The other one I think is really underrated is codebased abstraction. The abstraction provides the framework that auto research can iterate on and uh that's also that starting point hugely bias the whole search direction. This is a lot like a architecture design in neural networks. Different architecture in theory can represent the same function, but the architecture systematically makes some of the functions easier to be learned. And a good architecture biases the optimization towards solutions that generalize better, perform better, even when the training loss might looks the same. That's exactly the same for auto research.
Here's an example. We run auto research for a um fraud detection pipeline um and we trying to optimize the data prep-processing
and first we give it a loose API where the same function process both the training and testing data and the score looks great but the solution was polluted because there's a certain certain test set information got leaked to the training information. We then tighten the obstruction to a more strict API where the test data couldn't reach the training and the data leakage rate just dropped to zero. In this case, a good abstraction leads to better solutions. Even though if the agent really want they can steer reward hack. So my point is using auto research is a new craft. It's about the designing a here for an agent to climb and we are still very early on it. I think that makes this extremely exciting time to be an AI engineer. Other research will change what skills matter most. Creativity, the judgment to design a good eval or an abstraction. Those will soon get exponentially more important. Driving those system itself is where will be a new skill and that one is like barely existed one or two years ago. So the search is automated. the human would just move up the stack not out of it. Again, um we call is a auto research um product research lab. We we keep sharing what we are learning as we build uh on our blog and I will also post some of my thinking to on ax. If you think some of this uh useful to you, feel free to follow me on X. Thank you.