Parameter Golf with AutoResearch — Vayum Arora, Zhengyao…
Workshop on automating research loops, presented by Vayum Arora, Zhengyao Jiang, Dixing Xu, and Dhruv Srikanth of Weco AI. The session frames autoresearch as repeated proposal-and-evaluation cycles where an agent keeps code changes that improve a model's score and discards the rest. It covers the Aiden system and its contributions to OpenAI's Parameter Golf challenge, and uses Mini Parameter Golf to make training experiments small enough to inspect live. Key topics include what makes a search useful: fast, stable evaluations; a clear metric direction; time limits; initial guidance; and protection against reward hacking. The presenters demonstrate Weco's experiment tree for inspecting and steering running searches, address questions on reinforcement learning and multiple objectives, and close with a Flappy Bird controller exercise across varying conditions, illustrating evaluation design through a hidden validation set and edit restrictions.
# Video Identity Observations — "Parameter Golf with AutoResearch"
## Video Format & Setting
- This is a **live in-person technical workshop** (~two hours, hands-on), not a typical YouTube upload: *"Okay, we'll come back to Bay. Um, so here's how we'll spend the next two hours."* The session includes attendee laptop setup, Q&A ("question from the audience"), and a live competition.
- The speakers identify themselves and their affiliation early: *"My name is Vam. We have Jung Yao, Droo, and Dex"* — representing **Weco AI** (per the title; also referenced verbally as "WICO/WCO" and the "WICO dashboard," with signup at "dashboard.ai").
## Claimed Scope & Credentials (creator self-descriptions)
- **AutoResearch product claim**: *"auto research is basically a loop of a try and errors. You give a language model your code and a replayable evaluation script... it keeps the ideas that improve the score."*
- **Track record claims about their agent Aiden**:
- *"When OpenAI built MLE Bench, aid was one of the first agents they evaluated independently and on that benchmark it scored about four times the medal rate of the next best agent."*
- In OpenAI's Parameter Golf challenge: *"across more than a thousand... researchers, it became the number one contributor"*; *"Aiden landed seven... leaderboard records. That's twice the next best human"*; *"435 downstream PRs stated and built on Aiden's work"*; *"just 4% of the community's GPU compute."*
- Also: *"In April, our experimental research agent Aiden even won OpenAI's hiring challenge."*
- **Product positioning**: Weco's differentiators are framed as *structure* (tree-based search), *observability* (inspectable diffs per node), and *steerability* (injecting human ideas mid-run).
## Intended Audience (observable from presentation)
- **AI engineers and ML practitioners**, not general consumers: attendees are instructed to sign up for Weco and **Modal**, clone a repo, and run training loops — *"sign up for WO on dashboard.ai... modal... clone the repo... tell your agent to set up mini PG from the readme."*
- Comfort with technical vocabulary is assumed: *validation BPB*, *quantization*, *reward hack*, *RL/post-training*, *arXiv*, *CI/CD* — with audience questions like *"Can auto research apply to RL?"* answered at a practitioner level.
- A **competitive/gamified orientation** is used to engage this audience: a live "Flappy WO Cup" with *"the winner walking away with a really cool prize"* (a Nintendo Switch), run against a hidden validation leaderboard.
## Demonstrated Presentation Patterns (as distinct from claims)
- **Teach-by-doing structure**: conceptual framing ("anatomy of an auto research run": source file, eval, metric/goal, steps, timeouts, guidance) interleaved with live runs and a mini re-creation of the real challenge (*"mini PG... a scale model of the challenge"*).
- **Credibility-through-results storytelling**: repeated reliance on concrete competition metrics (PRs merged, compute fractions, cost-effectiveness multiples) rather than product feature lists alone.
- **Collaborative, humble framing of agent limits**: *"you might have context and intuition that an agent doesn't. At least for now, we believe it's important to find ways to fold human judgment into the system."*
- **Community/ecosystem signaling**: thanks to organizers (*"a huge thank you to Sean and the AI engineers worldfare"*), references to Karpathy's viral adoption, Shopify, and Browser Use as legitimacy anchors.
## Caveats
- All performance figures (4× medal rate, 7 records, 4% compute, 3.7× cost-effectiveness) are **creator claims from the transcript** and not independently verifiable from this material.
- No curated metadata beyond the title was supplied; names in the transcript are transcribed inconsistently ("Vam/Vayum," "Jung Yao/Jungao," "Droo"), so spelling should not be treated as reliable.
# Delivery Observation: "Parameter Golf with AutoResearch" Workshop
## Overview
A four-person technical workshop (Vayum/Vam, Zhengyao/Jungao, Dex, Dhruv) delivered live with hands-on setup, demos, audience Q&A, and a competition. Evidence below is drawn solely from the transcript.
---
## Tone
- **Warm, welcoming, and service-oriented.** The opening leans heavily on hospitality and gratitude:
> "a huge thank you to Sean and the AI engineers worldfare for having us. This is generally um a great room of AI and we're really really happy to be here."
- **Reassuring under friction.** When setup and internet problems arise, the speakers normalize them rather than apologize at length:
> "If you haven't been able to get set up yet, no worries. Uh we're going to have ample time to get it to to it later."
> "So, sorry about the internet problem. I think it's being worked on, but until then, I think it would be good to maybe go through uh the anatomy of an auto research run."
- **Playful when the stakes are low.** During the competition:
> "I don't know who Fern Nog is, but a little suspicious because there's only one node... we will be inspecting your runs to ensure that there's no cheating going on. Um, nice try."
---
## Vocabulary and Recurring Phrases
- **"Auto research"** is repeated dozens of times — it functions as the workshop's anchor term, defined early and reused consistently.
- **"Loop"** as a framing device: *"a loop of a try and errors"*, *"the agent is running in a loop on its own"*, *"automated the four research loop"*, *"while the loop is running"*, *"makes that loop possible."*
- **"Steer / steerability"** recurs as a signature concept: *"you basically steer um agent every single step"*, *"this is how you steer the agent from the start"*, *"steerability is essentially what makes that loop possible."*
- **"Single scalar metric" / "single number"** thinking: *"output a single scalar metric"*, *"drive down the same single number valp."*
- **Metric framing as direction:** *"and the low is better"*, *"is higher or lower better?"*, *"go is minimize."*
- **Soft hedges and discourse fillers** appear constantly: *"basically," "essentially," "uh," "um," "kind of," "sort of."* Examples: *"auto research is basically a loop"*, *"this is essentially when you stop watching and start to take over"*, *"essentially what makes that loop possible."*
---
## Teaching Habits
- **Concrete numbers as persuasion.** Nearly every achievement claim is quantified:
> "about four times the medal rate of the next best agent"
> "seven mer leaderboard records. That's twice the next best human"
> "just 4% of the community's GPU compute. It got 15% of total merged records. That's 3.7 times more cost effective."
- **Decomposition teaching.** The "anatomy of a run" section breaks the system into numbered pieces — source file, evaluation, metric, goal, steps, time bounds, guidance — and for each asks the audience a reflective question: *"So you really want to ask yourself two questions. Um what do I want to improve and is higher or lower better?"*
- **Anticipating failure modes.** The eval section warns proactively:
> "agents love to reward hack. So, they love to find holes in your evaluation protocol."
- **Rationale-for-constants habit.** Speakers explain *why* specific values were chosen:
> "we set it to be 210 seconds. And the reason for that is we give 60 seconds for uh training... 60 seconds for testing... and then 90 seconds which is a buffer."
- **Scale-down framing for learners.** The "mini PG" concept is explicitly justified pedagogically: *"think of mini PG as a scale model of the challenge."*
- **Metaphors to compress ideas:** *"let it boil the ocean for you"*, *"experiment graph"*, *"you can think of this tree as..."*, *"when you stop watching and start to take over."*
- **Clear handoffs between speakers**, signaled verbally each time: *"I'm going to hand it off to Dex"*, *"we'll come back to Bay. Thanks Janelle"*, *"I'm going to hand it over to Dex and Jungao."*
---
## Communication Patterns
- **Roadmap-first structure.** Early in the talk: *"here's how we'll spend the next two hours"* — a numbered agenda covering the challenge, setup, deep dive, demo, and competition.
- **Audience-interactive workshop rhythm.** Repeated practical support: *"feel free to scan the QR code... or uh, raise your hand and we'll come to you"*, *"check back in in around 15 or 20 minutes."*
- **Live Q&A handling.** Questions are read back verbatim before answering (*"Can auto research apply to RL? What is the scalar metric when there are multiple things to optimize?"*) and answered with concrete examples (*fraud detection* — hold accuracy, optimize precision).
- **Improvising under technical failure.** With internet down, the team pivots: *"we will be freestyling a little bit here. Uh hope you don't mind."* The demo then proceeds narratively rather than relying on live connectivity.
---
## Uncertainty and Caveats
- **Speaker attribution is uncertain.** The transcript does not consistently label which of the four speakers says what; observations about "the team" are safer than per-person claims. The opening speaker self-identifies as "Vam."
- **Some phrases may be transcription artifacts** (e.g., *"worldfare," "mer leaderboard," "the four research loop"* likely garble proper nouns like "merge"), so word-choice claims about those specific tokens should be treated cautiously.
- **Humor pattern evidence is thin** — the "Fern Nog" exchange is the clearest joke; a single instance is not enough to claim a stable humor style.
- Repeated concepts ("loop," "steerability," quantified results) appear across multiple sections and speakers, making them the highest-confidence stable patterns.
# Parameter Golf with AutoResearch — Observation Record
## Session Overview
Workshop by the Weco AI team (Vayum "Vam" Arora, Zhengyao Jiang, Dhruv, and Dex/Dixing Xu) covering auto-research systems, the Parameter Golf challenge, and a hands-on Flappy Bird competition. Session conducted with acknowledged internet/connectivity problems; some demos were "freestyled" via mobile hotspot.
---
## Speaker: Zhengyao Jiang (background on auto-research)
### Core concept claim
- **Auto-research is "a loop of trial and errors"**: a language model is given code and a replayable evaluation script; it repeatedly proposes ideas, tests them against the eval, keeps improvements, and discards the rest.
- Example metrics cited: **accuracy, speed, cost**.
### Historical claims
- Similar loops existed in academia "like two years" but went viral after **Karpathy** posted about applying it to his model training scripts with good results.
- Use cases spread within weeks to backend engineering, prompt/agent engineering, model inference speedup, and production — e.g., reducing latency of **Shopify's CI/CD pipeline** and improving the **Browser Use** agent.
### Qualification / warning
- Auto-research is "hard to master": with a normal coding agent you steer every step, but auto-research runs autonomously in a loop — a "much bigger multiplier on your prompt and your setup."
- > "Pointed at the right eval you basically let it boil the ocean for you, but otherwise you're just burning through all your LLM tokens."
---
## Speaker: Vayum Arora (team background, agenda)
### Team track record (claimed)
- Released **Aiden** in April 2024, an autonomous ML engineering agent (write code, run experiments, read results, keep improving).
- Claim: on OpenAI's **MLE-Bench**, Aiden scored "about four times the medal rate of the next best agent."
- Claim: Aiden became the **number one contributor** to Parameter Golf across more than 1,000 researchers.
---
## Speaker: Dex (Dixing Xu) — Parameter Golf
### Competition structure (as described)
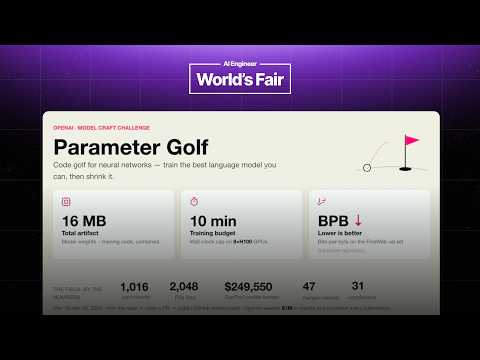
- OpenAI's **model crafting challenge**: train the best language model under two hard constraints:
- Model weights + training code must fit in **16 MB**.
- Training must finish within **10 minutes**.
- Scored by **bits per byte (BPB)** on the FineWeb validation set; lower is better. OpenAI provided baseline dataset, eval scripts, and $1M in compute credits; everything open-sourced.
### Participation stats (as stated)
- 44-day competition; ~1,000+ researchers; 248 PRs; ~250k GPU compute burned; only **47 PRs merged as records** from 31 contributors.
### Aiden's results (claimed)
- Built as a self-improving multi-agent system (Claude + GPT model families) running indefinitely to climb a single metric; pipeline: pull papers from arXiv, implementations from GitHub, its own past logs → propose, test, audit for legality, keep working ideas, write implementation, run experiments, submit PRs past quality gates.
- Landed **7 merged leaderboard records** — "twice the next best human."
- Highest **OPR/H-index** in the competition — claimed to indicate reusable work others built on (**435 downstream PRs**).
- Used **4% of community GPU compute** for **15% of total merged records** — "3.7 times more cost effective than the field average."
---
## Speaker: Dhruv — Anatomy of an auto-research run (Mini PG)
### Components (framed as a general contract for most auto-research systems)
1. **Source file** — defines the search space (single or multiple files); in Mini PG, `solution.py` defines model config and training dynamics.
2. **Evaluation** — called "probably the most crucial part": output a single scalar metric; eval should be **fast, cheap, low-noise**, enabling more steps under fixed budget and confident hill-climbing.
3. **Metric and goal** — two questions: what to improve, and is higher or lower better? (Mini PG: minimize validation BPB.)
4. **Number of steps** — hard to know a priori; 20 chosen for the workshop; "more ideas tried generally leads to more breakthroughs."
5. **Eval time bound** — set to **210 seconds** (60 training + 60 testing + 90 buffer for Modal GPU spin-up/overheads), because loops stall, hardware fails, and bad agent code can hang the system.
6. **Initial guidance** — encode domain expertise (hard constraints, promising directions like compression, quantization, weight sharing) via a markdown file.
### Key warning (reward hacking)
- > "Agents love to reward hack... they love to find holes in your evaluation protocol, holes in your benchmark."
- Mitigation: make the eval as robust as possible.
### Production-grade properties (claimed)
- **Structure**: tree-based search so ideas compound instead of starting from scratch.
- **Observability**: open any attempt, read the exact diff behind its score.
- **Steerability**: inject ideas mid-run, set per-node budgets; "we believe it's important to find ways to fold human judgment into the system whenever it's necessary."
### Steerability case study (Parameter Golf, as narrated)
- Aiden's score plateaued for five days (April 15–19) despite trying new attention, compression, richer stacks.
- A human community member shipped a new tokenizer; within **eight hours of that PR merging**, Aiden fused it with its existing work and made "the biggest jump in weeks."
- Framing: "less of a set it and forget it... it's a collaboration where we steer the agent."
---
## Speaker: Zhengyao Jiang — setup walkthrough & Q&A
### Mini PG description
- A shrunken "scale model" of Parameter Golf: real LM training, same fixed evaluator, same val-BPB objective, but tiny dataset and minutes-long eval.
### Q&A responses
- **Can auto-research apply to RL?** Yes — cited a project ("sobound"/speedr runner, transcription unclear) applying it to post-training RL scripts for game-playing agents.
- **Multiple objectives?** Combine into a single metric: weighted sum, or treat some metrics as **constraints** while optimizing one (e.g., fraud detection: hold accuracy, optimize precision; Parameter Golf: model size as constraint).
---
## Speaker: Vayum Arora — Flappy Weco Cup competition
### Setup (as described)
- Flappy Bird variant: a `should_flap` controller decides each frame whether to flap; optimize the controller; metric is average score.
- **Four worlds**: normal, moving gap, wind, variable (mix of all). Score is averaged across all four — "a controller that does well in a normal game but dies in the wind won't win."
- Leaderboard uses a **hidden validation set** — "you can't obviously overfit on the public game."
### Rules
- Only edit `controller.py`; keep `should_flap` signature exactly.
- No touching game/evaluator; no imports, external libraries, file I/O; no parallel compute; everyone on the same model (Opus 4.8, transcription uncertain — possibly "Opus 4.8").
- Originally 30 minutes; extended to end of day due to connectivity issues. Prize: a Nintendo Switch, winner contacted via email in team name.
### Anti-cheating note
- Suspicion voiced toward a leaderboard entry ("Fern Nog") with only one node: "we will be inspecting your runs to ensure that there's no cheating going on."
---
## Contradictions & Qualifications Preserved
- Internet failures repeatedly degraded live demos; the team explicitly "freestyled" and one steering demo failed mid-session ("I don't think it's connected. I think Claude didn't follow the instruction").
- Agent's scores/nodes in the demo (root at 3.93 BPB) were shown live but the demo was partially broken.
- Baseline-vs-golf numbers: real challenge root baseline cited as 0.5 in one walkthrough (Dhruv's tree example) and 3.93 in the live Mini PG demo — these are different runs/tasks, not directly comparable.
- Step budget for the competition was stated as ~50 steps, then immediately revised to "unlimited steps until the end of the day" given the extended timeframe.
# Speaker & Provenance Record — "Parameter Golf with AutoResearch"
## Identified Speakers & Roles
| Speaker | Role | Notes |
|---|---|---|
| **Vayum ("Vam/Vayum") Arora** | Co-presenter, Weco AI | Opens the session, thanks hosts, introduces team and agenda |
| **Zhengyao ("Jung Yao/Junga") Jiang** | Co-presenter, Weco AI | Gives background on autoresearch basics; later co-demos setup with Dex |
| **Dixing ("Dex") Xu** | Co-presenter, Weco AI | Presents the Parameter Golf competition breakdown; co-leads setup demo |
| **Dhruv ("Drew") Srikanth** | Co-presenter, Weco AI | Introduces team background (Aiden, MLE-Bench); discusses tree-based search, observability, steerability |
| **Sean / "AI Engineers Worldfare"** | Event hosts (mentioned, not speaking) | Organizers of the event where the workshop took place |
| **Unnamed audience members** | Question askers | Asked about light mode, applying autoresearch to RL, multi-objective metrics |
| **"Fern Nog"** | Competition participant (mentioned) | Flagged by presenters as potentially suspicious scoreboard entry |
> Note: Spelling of names varies in transcript ("Vam," "Jung Yao," "Junga," "Janelle," "WO/WICO/Weco"); canonical names taken from video title metadata.
## Third-Party Claims & Referenced Sources
- **Karpathy** — credited with viralizing the try-and-error research loop via his model training scripts (~2 years after it existed in academia).
- **Shopify** — cited as production example: latency reduction in CI/CD pipeline.
- **Browser Use (company)** — cited as production example: improvement to their browser agent.
- **OpenAI hiring challenge "Prime Golf" / Aiden win** — Aiden (their experimental research agent) claimed winner, April.
- **MLE-Bench (OpenAI)** — Aiden claimed ~4x medal rate of next best agent when independently evaluated.
- **Parameter Golf (OpenAI model-craft challenge)** — constraints: 16 MB artifacts, 10-min training; scored by bits-per-byte on FineWeb validation set; 1,000+ researchers, 248 PRs, ~250k GPU compute burn, 44 days, 47 merged records, 31 contributors, $1M in compute credits.
- **Aiden claims**: 7 merged leaderboard records (2x next best human), highest h-index, 435 downstream PRs built on it, 4% of community GPU compute, 15% of merged records, 3.7x cost effectiveness. *(Self-reported by presenters — flag as vendor claims.)*
- **"Sobound / speedr runner" project** — referenced as an RL post-training example applying autoresearch.
- **FineWeb** — original dataset of real Parameter Golf; replaced by a "tiny data set" in workshop's mini-PG.
## Promotional Segments (flagged)
- **Weco / Wico autoresearch product** — the entire workshop doubles as product demonstration: dashboard, tree-based search, observability, steerability, "bridged session" with Claude Code.
- **Modal** — compute partner; free credits promoted via code (`modal.com/signup`, `modal.com/credits`).
- **Weco sign-up** — promoted at `dashboard.ai` (transcript garbled).
- **Prize** — Nintendo Switch for Flappy Wico Cup competition winner; entries tied to email/team name.
- **Wednesday talk** — Vayum promotes his separate upcoming talk about Aiden.
## Workshop Materials & Availability
- **Mini Parameter Golf (mini PG)** — scaled-down version of Parameter Golf; repo clone + README instructions given; `solution.py` as source file; validation BPB metric; 20 steps; 210s eval timeout.
- **Flappy Wico Cup competition** — `controller.py` / `should_flap` only; four worlds (normal, moving gap, wind, variable); hidden validation leaderboard; rules: no touching evaluator, no external imports/file IO, no parallel compute, all participants on same model ("Opus 4.8" as stated).
- **Competition duration** — extended to midnight (end of day); winners contacted via email.
- **Q&A channel** — Slido and QR code mentioned; raised hands in-room.
## Contextual & Uncertainty Notes
- Transcript is auto-generated with heavy name/term corruption (e.g., "RM tokens," "rebel" for repo, "435 downstream PR stated," "paraent golf," "fine wide" likely FineWeb).
- Technical glitches noted: venue internet outage (mobile hotspot used), Modal payment issues reported by attendees.
- Exact URLs, dates, and numeric figures (e.g., "6 researchers," "105 minutes") are garbled in transcript; treat specific numbers as approximate.
- Cheating check: presenters state they will inspect runs (specifically the "Fern Nog" single-node entry).
- No curated metadata beyond title supplied; comment availability not addressed in source.
Uh, welcome. Please grab a seat if you haven't already. My name is Vam. We have Jung Yao, Droo, and Dex. Before anything else, uh, a huge thank you to Sean and
the AI engineers worldfare for having us. This is generally um a great room of AI and we're really really happy to be here. Um if you haven't been able to get set up yet, no worries. Uh we're going to have ample time to get it to to it later. Um Junga will give us a brief background on the basics behind auto research. Okay. Um in case any of you still don't know uh auto research is this is just a quick brief. So auto research is basically a loop of a try and errors. You give a language model your code and a replayable evaluation script. It will keep trying ideas and test them against the eval and it keeps the ideas that improve the score and discard everything else. So some example metrics includes accuracy, speed uh and cost. Similar loop has been exist uh in academic for a while like two years but it really got viral in this year when Kapasi uh posted about it in his model training scripts and turned out works really well for him. In just a few weeks, it just the use case of auto research spread from training to everything like a backend engineering, prompt and agent engineering, speed up model inference and it also quickly show up in production. For example, it reduce the latency of Shopify's CI/CD pipeline and improve the browser use the company's browser use agent. In April, our experimental research agent Aiden even won OpenAI's hiring challenge uh called the prime golf uh which we will tell you a bit more soon and uh I also have a talk on Wednesday specifically about it. Um so okay auto research can be really powerful but it's also hard to master with a normal coding agent you basically steer um agent every single step but for auto research it's like the agent is running in a loop on its own so it's much bigger multiplier on your prompt and your setup pointed at the right eval you basically let it boil the ocean for you, but otherwise you're just burning through all your RM tokens. Um so hopefully this workshop will give you a good starting point to learn about auto research and um apply that in your own work. Okay, we'll come back to Bay. Thanks Janelle. Um so here's how we'll
spend the next two hours. Um, Dex will take you inside parameter golf, uh, the challenge that we entered our agent into. Um, what that challenge was actually all about and how our agent
ended up as the most influential contributor. Um, then it's your turn. Uh, we'll get you set up and kick off an auto research run on your laptop. While your auto research is running in the background, we'll break down the basics of an auto research loop and the pieces that actually shape what an agent does. Um, and we'll go deeper and do a guided demo where you're able to run, steer, and inspect what your agent is doing live. And we'll finish with a fun part, which is a live competition. Um, you'll take everything that you learned today, point auto research at a game that we've all played before, and go head-to-head to see whose agent can get the highest score uh, with the winner walking away with a really cool prize. a little bit more on who we are. Um, so we've been working on auto research for quite some time now. Before WICO, uh, we released aid in April 2024, which was an autonomous ML engineering agent. The basic idea was give it a machine learning problem, let it write code, run experiments, read the results, and keep improving. When OpenAI built MLE Bench, aid was one of the first agents they evaluated independently and on that benchmark it scored about four times the medal rate of the next best agent. More recently, as we discussed, we pointed our agent to parameter golf and across more than a thousand research it researchers, it became the number one contributor. I'm going to hand it off to Dex who's going to tell us more about the competition.
Hello everyone, my name is Dex. Uh so I'm going to talk about the paramet golf. So paramet golf is open as uh model craft challenge. The goal is to
train the best language model you can under two hard constraints. uh once the four artifacts including model weights plus training code has to fit in 16 megabytes and the training has to finish within 10 minutes. Submissions are scored by bits per bpb on the fine wide validation set and the low is better. Openi provided a baseline data set and evaluation scripts so participants can for the ripple improve the model and submit their result through GitHub. So everything is open sourced. They also put up a million dollar in computer credits and reviewed every submission. During the 44 day competition, there were,6 researchers entered and filed 248 PR roughly about uh 250k of GPU compute burn. The final lead board is short. Only 47 PRs merge as records from 31 contributors. And for this competition, we build Aiden, a self-improving multi-aging system based on the cloud and GPT model families that run indefinitely to help clamp on a single metric. In permit golf, Aiden automated the four research loop. It pulls public page papers from archive, strong implementations from GitHub and its own part logs. Then propose new ideas, tests them, audit them for legality, keep the ones that work, write the implementation and run the parents. Once the results, clear the quality gates, it will create and submit a PR for review. And the results are remarkable. Aiden landed seven mer leaderboard records. That's twice the next best human. It also had the highest OPR H index in the whole competition which means Aiden didn't just produce accept records. It published reusable work that other participants kept building on 435 downstream PR stated and built on Aiden's work and it got there on a fraction of the budget from just 4% of the community's GPU compute. It got 15% of total merged records. That's 3.7 times more cost effective than the field average. And this wraps up a how Aiden becomes the number one contributor to the open herring challenge. Thank you. Cool. So, we're actually going to run
auto research on a version of the same parameter golf challenge that Dex just walked you through. Uh, for future reference, we will just call this mini PG, which stands for mini parameter
golf. Um, as Dex discussed, the real parameter golf competition was heavy. Every single experiment was training a language model on a massive data set, which is fine when the competition is over four weeks, but in a workshop like today, you'd never actually be able to see your auto research run. So, think of mini PG as a scale model of the challenge. uh you're still going to train a real language model, score it on the same fixed evaluator, and drive down the same single number valp, which is essentially measuring how well the model predicts text it hasn't seen. But what we did is we shrank this in scale. We're using a tiny data set instead of fine web and training an eval that only takes a few minutes. So you'll actually be able to get a loop going and see several steel several real steps live. So before I get to the instructions on the next slide, just a little bit of
orientation. Um you're going to run auto research yourself on mini parameter golf. You're going to sign up for two platforms if you haven't already. One is we our auto research agent that runs a
search and the other is modal uh the compute your experiments train and evaluate on. Free credits. Thank you modal. Um then you will clone our parameter golf repo uh and hand it to your coding agent. tell it to kick off a run. It handles the setup and it'll start the loop. Once it's going and it's running in the background, uh you can kick it off and we will check back in in around 15 or 20 minutes to take you inside the details. Instructions are here. Um sign up for WO on dashboard.ai. Um modal for moto modto.com-signup. Uh there's a code to claim your modal credits. Um, if you already have a modal account, you can go directly to modal.com/crediteds and enter your code there. Um, and once you're done with those two steps, uh, clone the repo shown here, um, and tell your agent to set up mini PG from the readme and kick off a run. If you run into any issues or have any questions, feel free to scan the QR code and enter it there and we'll be monitoring that or uh, raise your hand and we'll come to you. check back in in around 105 minutes. Thanks, guys. \>\> Uh, all right. So, sorry about the internet problem. I think it's being worked on, but until then, I think it
would be good to maybe go through uh the anatomy of an auto research run. And we're going to be doing this in the context of uh WCO as the auto research
system and mini PG as the task. But really, this this kind of contract that we have here is fairly general. Most auto research systems are going to have you ask very similar questions and uh think about the same things. Okay. So the first thing is the source file. Uh this is what the agent actually has to modify. This defines the search space and where it can make changes. So this can be a single file, it can be it can be multiple files. In the case of minip it's uh this one file called solution.py and solution.py PI essentially defines the model config and the uh uh the training dynamics that's going to go on while the model is training.
And then the second thing and in my opinion this is probably the most crucial part of an auto research system is the evaluation. And so you want to have a very simple way of allowing your
auto research system to evaluate every solution that it generates. Um, and you want to have it output a single scalar metric. And you want the eval to be fast, you want it to be cheap, you want it to have low noise. Uh, because this essentially leads to your ability to run more steps if you have a fixed budget or a fixed time constraint. Um, and if there's low noise, then both you as well as the agent are more confident as you're kind of hill climbing on, uh, whatever task you're, uh, autoresarching on. And so, uh, one thing to be aware of though is agents love to reward hack. So, they love to find holes in your evaluation protocol, holes in your
benchmark. And so, you really want to figure out how to make your eval as robust as possible. The next two things are the metric and
the goal. So you really want to ask yourself two questions. Um what do I want to improve and is higher or lower better? Um and in our case for mini PG, you want to minimize the validation BP. So you essentially want to find a model that is better at predicting on unseen text. The next thing is the number of steps you actually run the auto research system for. This is a bit tricky because it's difficult to know a priority how many steps you should give your your system. We've chosen 20 in this case just because we want to give your agents enough time to kind of explore different ideas and you can you can see what the agent is actually exploring, what works, what doesn't. Um but really more ideas that gets tried uh generally leads to more breakthroughs. And so uh this goes back to what I was saying earlier where if you have a fast eval um or if you have a cheap eval then when you're under some kind of time constraint or cost constraint, you can run more steps. Um and so uh again the eval is is always super important to uh consider. All right. So you also want to bound the
uh time for which your eval runs for uh because a lot of things can go wrong. So loops can stall, hardware can fail, uh sometimes the agent will produce really bad code that causes the entire system
to hang. And so you want to bound the the actual evaluation running. Um in our case, we set it to be 210 seconds. And the reason for that is we give 60 seconds for uh training the model, 60 seconds for testing the model on unseen text and then 90 seconds which is a buffer for you know modal to spin up the GPUs for training, spin it up for um uh for the testing and any other kinds of uh overheads that exist. And the last thing is the guidance that you give the agent at the start of your optimization. Uh so this is how you steer the agent from the start. And you really want to think about it as you know you've probably run experiments before. You've compounded a bunch of domain expertise and human knowledge. And you might have some ideas about things that work, things that might be interesting to try and maybe things that don't work. And so this is where you can provide that kind of guidance. Um in the case of WICO, you can simply point it to a markdown file, have all of your information and context in there. Um and the agent is able to use this and uh it gives the agent the best chance at uh at finding success. Um, in the case of mini PG, this can be uh some hard constraints or different ideas that seem to work quite well like uh focusing on compression uh different quantization methods uh maybe even weight sharing across different blocks in the model.
Um we are just going to demo how to get started on auto research for you considering the internet issues. Um before we get to that a little bit more
about what we think um makes auto production grade auto research actually production grade. Um the first is structure. So uh we have a treeb brace search uh where the agent shows you every attempt it's run so that ideas as duv had mentioned can sort of compound on each other instead of starting from scratch. The second is observability. Um you can sort of open any attempt read the exact code change behind its score so you can see why the agent is taking the approach it is. And the third thing is steerability. So you have a sense of control. You can inject your own ideas and knowledge while the loop is running and have it try new directions in case it's stuck. A little bit more about the treebased
search. Um we will shortly demo this on our auto research dashboard, but um treebased auto research essentially treats the problem as a structured optimization process over code. Uh it
starts with the root of the tree. As you can see the score was 0.5 um which is just the baseline program and a measured score. Every node after that route is a modified version of the code run against your eval with a score attached. You can think of this tree as an experiment graph. As you can see the search builds on what works. We're finding good candidates and pruning bad ones. So when a branch improves a score it builds on those ideas and goes deeper next. which means that you can inspect the exact changes your auto research system is making and build off of those. So the next idea we talked about was observability. Um because you can see every one of the nodes in this treebased search, you can open any one of them and see exactly what changed. You can see your metric move in real time correlating to a movement correlating the movement to a reason. You can hover over over a node, get a summary of what changed, and you can open it and read the exact diff. So when the metric jumps, you can read the change that caused it. And typically, these runs go for hours across hundreds of experiments. So once you can see what it's doing, the next natural step is to be able to change what it does. This is essentially when you stop watching and start to take over. Um, if I have an idea I want to try in plain English, um, I take the idea, it opens a new branch and you can see it try this new idea and have new nodes develop and a new curve. I can also put a budget to each node so it spends compute where I want. And this is the part that made it usable on real problems because you might have context and intuition that an agent doesn't. At least for now, we believe it's important to find ways to fold human judgment into the system whenever it's necessary.
I want to ground that point uh steerability in something real. Um because parameter because in parameter golf steerability was a big part of why we did well. Um this is an actual
breakthrough from the competition. It started with our agent uh which is the line in pink. um for five days from April 15th to April 19th. Uh it kept trying new things, um new attention, compression, a richer stack, but the score essentially plateaued. There was a human in the community uh that shipped a clever new tokenizer, which is the blue line. Um, and within eight hours of emerging that change, our system picked it up, fused it with the pieces it had already been working on, and shipped the biggest jump in weeks. Running auto research on something this hard is less of a set it and forget it. Uh, it's a collaboration where we steer the agent. We pull in ideas from the people around us. And steerability is essentially what makes that loop possible. It's how real breakthroughs actually happen. Um, I'm going to hand it over to Dex and
Jungao to talk a little bit more about how to get auto research set up. Um, we'll essentially mimic the process that you guys were trying to do on your laptops. \>\> Okay. Um, so what we are going to do
here is we just walk you guys through the high level idea like how how does it happen? We just use our mobile hotspot. Um so we will be freestyling a little bit here. Uh hope you don't mind. Um so yeah can you just uh yeah okay maybe we can also walk through the whole doc being fed to uh claude. So \>\> yeah. So basically uh so you can go into the rebel and some like simple instruction like start the wo raw based on the readme and it should be like if the internet is good I think it should start the uh default wle run and uh we can also go over via the like the how is the wle command working. Yeah, this case you have a source file. The solution is basically the training script of mini PG. I assume like a eval command is I think Z also mentioned this is additional guidance or prompt that will guide the whole uh search process and the metric is a validation BPB. Uh this is like a hold out um uh loss like a loss only hold out set. Uh go is minimize and others are just configs we just mentioned. Oh, sorry. Eval commander is actually the the bash command that uh you're going to run the uh uh run the eval and eventually it will output a uh score like it print a score to the terminal and it's going to be passed by the agent and that's the key uh signal that will drive the whole tri and error loops. \>\> Yeah. Um in meanwhile I can also show the dashboard. So if you go into the W dashboard um and I think there I did some wrong and you you basically see a lot of things and uh after the the command like auto booted by the agent um I think then you you will see the romping popped up and then you can try out the features we provide. Yeah. Um, do we have a run just to get started? \>\> Yeah, I think it's just starting. \>\> Okay, still running saying um yeah, Claud is working. Uh question from the audience while you guys are doing that. Um one, is it possible to turn up the brightness on the dashboard or switch to light mode? \>\> Start again. \>\> I'm I'm right here. Can you turn the light mode on the dashboard? It's a little hard to see. \>\> I see. Light mode. Forgot. Where is it? Is there
uh second question is can auto research apply to RL? What is the scalar metric when there are multiple things to optimize?
\>\> What is the \>\> can auto research apply to RL? What is the scalar metric when there are multiple things to optimize? \>\> I see. Yeah. Um it can definitely be applied to IO like apply to IO training scripts. Um I think there is a um derived a project called sobound uh speedr runner that's actually exactly doing it like for post training aquin model uh for playing a game and uh yeah in that project you can apply auto research to the uh IR IR training scripts And um the second question you have a multiple objectives to optimize for. Um the idea is you eventually just combine them to a single metric like you either apply different weights on those different metrics or you treat some of the matrix as constraint and optimize for one of them. For example, if you're doing things like fraud detection, you might hold the uh accuracy and trying to optimize the precision. Um and uh for parameter golf exactly you hold the model size as a constraint and you optimize for the accuracy of the system.
Yeah, we can see the um agent already generated uh one node. So the zero zero node is
basically the root node the baseline solution and 3.93 means the validation BPB attached to that solution and uh you can see the wos auto research already generated one node here um um here we also have a summary of the uh ideas it's tried And uh seems like already getting improvement. Oh yeah, you can also \>\> also open the code and see what's actually been changed. \>\> Yeah. Do we have a stability? \>\> Okay. Uh for stability you can basically tell the agent for example say like uh explore the quantization method. Is it connected? \>\> Yeah. Uhization method do not change the not just change the model config because we don't like just want to do the hyperparame tuning. We also want to try like more aggressive method. \>\> I don't think it's connected. I think clock didn't follow the instruction. Yeah, basically we also support you bring your claw code agent to our dashboard. We call it a bridged uh session. Um so basically yeah you can you can see the dashboard the tree structure the metric and the uh clock code at the same time and then you can tear clock code okay this is the uh the direction I want to steer the whole uh search process to \>\> checked in with some of you I think internet might be a little better uh
some of you guys are using hotspot I know there's some modal payment issues. We're going to move on to the final part which is the competition aspect. Uh you don't need modal for this and originally
this was designed to be a 30inut competition but we will give you guys until the end of the day um a little bit more on what this is. You guys have all played Flappy Bird. Um we're going to do a Flappy Wo Cup. So essentially, everyone hopefully has played Flappy Bird. You tap to flap. You dodge the pipes and you fly as far as you can. And your final score is dependent on how far you fly. We have turned this into an auto research problem. So instead of playing it, there's a controller called should flap that decides every frame whether the bird should flap. Your job is to optimize that controller. The metric is the average score and you want that as high as possible with the highest score winning. With all games, there's a twist. Uh we're not just running this on Flappy Bird. Uh we're running this across four different worlds. So the first world is
normal, which is the classic game. The second is moving gap where the pipe gap drifts up and down. The third world has wind pushing the
bird around. And the fourth world is variable which mixes all the conditions. Your score is the average across all four of these worlds. So you can't just focus on one. Um a controller that does well in a normal game but dies in the wind won't win. And the leaderboard scores you on a hidden validation set that you never see. So you can't obviously overfit on the public game. A few rules uh mostly so it's fair and it doesn't break. Uh you only and we will share the GitHub repo for this shortly. Uh you only edit the controller which is a controller.py. You keep you should keep should flap signature exactly as it is. So you can't touch the game or the evaluator. No imports, external libraries, file IO. So we're keeping this self-contained. And in the spirit of keeping it fair, uh, no parallel compute allowed. So you would be using WICO for auto research. Um, everyone is defaulted to the same model, Opus 4.8. So it's a level playing field. And remember, the local score that you see on your laptop isn't going to match the leaderboard because of our hidden test set. Some tips. Um, you'll get about 50 steps on WCO. Uh, actually this is with the 30 minute time time frame. So, uh, I guess you can run unlimited steps until the end of the day. Um, can start from the baseline. uh the baseline already works. So improve the code rather than rewriting the controller. Uh think about making small focused edits. Um things like tuning the safety margin, the velocity keyboard, the bottom buffer, adjusting the behavior per world and um maybe implement some of the features we talked about today. Whether it's inspecting nodes that scored well, building on them, bringing in ideas from outside, um, and trying several
directions. This is the instructions for the game. Um, by the way, you guys are playing for
a Nintendo Switch. Uh the way that we're going to determine who wins is for your team name, put in your email and by the end of the day, the highest score uh we will reach out to the person that that is. In the meantime, we're going to continue answering questions from our Slido or uh please raise your hand if you have any questions. Okay, we're just about to wrap up here. Um scores look like they're coming in. I don't know who Fern Nog is, but a little suspicious because there's only one node and so we will be inspecting your runs to ensure that there's no cheating going on. Um, \[laughter\] nice try. Uh, we will be opening this competition uh till midnight tonight. um we will find a way to get to you can put in your email or we're also we also have your emails uh from the runs that you guys are doing or you can just contact us on our website. But um feel free feel free to keep going at it. And um thank you all for coming. \>\> \[music\]